· Prakash Natarajan · Reliability
Escalation Rate for AI Agents: What Actually Drives It
Escalation rate for an AI agent is driven by a confidence threshold, not ticket complexity. The formula, real benchmarks, and the reopen-rate trap.
Escalation rate for an AI agent is driven by a confidence threshold, not ticket complexity. The formula, real benchmarks, and the reopen-rate trap.
Most agent evaluation guides stop at plan quality and tool correctness. Here's the fourth layer they skip: turning an eval score into a number your own customers can see.
CrewAI and LangChain both get a demo working in an afternoon. The real difference shows up once you need to trace a wrong answer, test the agent, and keep one customer's data out of another's.
Semantic Kernel and LangChain look close to interchangeable on a feature table. The gap that actually costs you time shows up later, in tracing, testing, and running one agent for more than one paying customer.
AI agent guardrails block a specific action before or during execution. Here's what they cover, how to test one before it ships, and what breaks once you have more than one tenant.
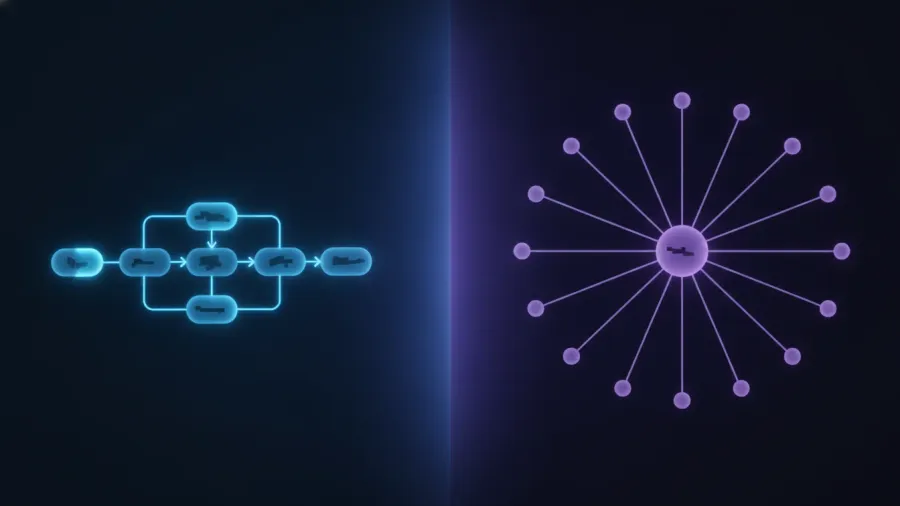
LangChain and LlamaIndex split on orchestration versus retrieval, but the choice that actually costs you later is which one is easier to trace, test, and isolate per tenant. Here's the real comparison, plus where CrewAI fits.